Vision & Image
Image generation, editing, restoration, OCR, and visual understanding. 252 releases.
252 releases
 Open ↗
Unlimited OCR 2
Since Week 30 2026: Baidu released Unlimited OCR 2 on 27 October 2026, a follow-up to its Unlimited-OCR document…
 Open ↗
Ideogram Vector
A new Ideogram model that outputs editable SVG vector artwork for logos, print designs, illustrations, labels and…
 Open ↗
Fibo 2.0 Dev
The next generation of Bria's FIBO image models, and the first to put image editing and text-to-image in one set of…
 Open ↗
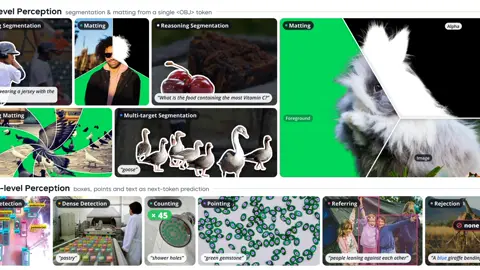
WeVisOne-VL
A vision-language model from Tencent's WeChat Vision team that handles detection, referring localization, counting,…
 Open ↗
AI Toolkit
Ostris's long-running toolkit for fine-tuning and training LoRAs on diffusion models, with a web UI and a self-updating…
- Open ↗
MOSS-Image
An open text-to-image model family from the OpenMOSS team, announced 16 October and built on a 5B-parameter DiT…
 Open ↗
FLUX 3 Image Klein
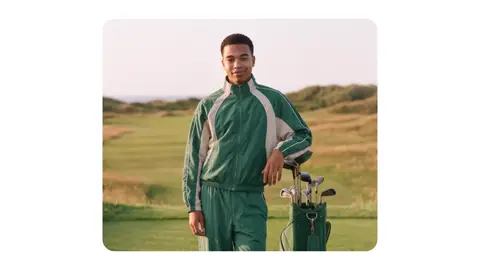
A 5.6B-parameter, open-weights member of the FLUX 3 Image family (covered in week 41) that runs on a single consumer…
 Open ↗
Krea 3
Krea's new image editing model, launched 15 October.
 Open ↗
Nemotron 3.5 Super VL
A vision-language version of the 120B-total, 12B-active hybrid Mamba-Transformer mixture-of-experts behind Nemotron 3…
 Open ↗
ArtCraft Crafting Apps
The team behind ArtCraft, an open-source AI image and video studio, launched seven free native desktop apps written in…
 Open ↗
Iris-3B
A 3B-parameter text-to-image model, released 7 October, that generates pixels directly with no VAE or latent space, at…
- Open ↗
Nano Banana 2.1
Google's new image generation and editing model, announced 6 October and built on Gemini 3.6 Flash, following Nano…
 Open ↗
Vision Demos
Six practical computer-vision demos on sport and fitness footage: dance-sync scoring between dancers, chin-up counting…
- Open ↗
PixelUMM
A unified model that both understands and generates images and video from raw pixels with one decoder-only Transformer…
 Open ↗
Ideogram 4.5
An image editing model released 30 September for multi-turn work.
 Open ↗
FLUX 3 Image
The image model in Black Forest Labs' FLUX 3 family, launched 1 October, following FLUX 3 (week 30) and FLUX 3 Action…
 Open ↗
Supra2-IMG
A small text-to-image diffusion transformer at 104.1M parameters, generating 256x256 images using a frozen Flan-T5-Base…
 Open ↗
Ovis-Embedding
A collection of universal omni-modal embedding models: Ovis-Omni-Embedding-3B, Ovis-VL-Embedding-2B and…
 Open ↗
Ming-Image-0.1-Design
A 6B text-to-image model specialised for text-rich visual design output such as UI, infographics and posters, with RGBA…
 Open ↗
Qwen-Image-2.1
An open-weight text-to-image and image-editing model with a 7B visual generation component, adding native transparency…
 Open ↗
RADAR
A generalist vision-language model for abdominal CT diagnosis, trained on more than 400,000 contrast-enhanced CT…
- Open ↗
LightOnOCR-2-1B
Moved from Week 4 2026, and unchanged since: the model card and its arXiv paper are both dated 19-20 January 2026 with…
- Open ↗
Unlimited-OCR
Baidu's document-parsing vision-language model, built on a DeepSeek-V2-derived mixture-of-experts backbone routing 6…
- Open ↗
InternLumina-U2
A multi-codebook diffusion LLM unifying text, image, video and 3D understanding with image generation and editing in a…
- Open ↗
LLaDA-Image
A 6B diffusion text-to-image and instruction-editing model where both the backbone and the DiT are diffusion models…
- Open ↗
Fibo-1.5
An 8B-parameter DiT flow-matching text-to-image model, distilled from Bria's FIBO and keeping its structured-JSON…
- Open ↗
Bit Depth Enhancement (BDE)
A running index of bit-depth enhancement research - showing low bit-depth content on higher bit-depth displays without…
- Open ↗
DeepSeek vision API
Image understanding arrives on deepseek-v4-flash-vision-exp, taking JPEG, PNG, GIF and WebP by base64, HTTPS URL or…
- Open ↗
SenseNova-U1.5-8B-MoT
Built on the NEO-unify architecture, which drops both the visual encoder and the VAE so understanding and generation…
- Open ↗
UniFace
One Python API across 15 face-analysis tasks that normally means stitching five libraries together: detection via six…