Audio & Speech
TTS, STT, voice cloning, music generation, and audio processing. 172 releases.
172 releases
- Open ↗
Audio8-TTS-Realistic 0.6B
Audio8-TTS-Realistic is a 0.6B-parameter text-to-speech model, built on Audio8-TTS-Preview.
 Open ↗
NVIDIA Nemotron 3.5 Transcribe 30B-A4B
Nemotron 3.5 Transcribe is an open-weight, offline speech and audio model from NVIDIA.
 Open ↗
Hy-SimulMT
Hy-SimulMT is a real-time simultaneous translation model from Tencent Hunyuan.
 Open ↗
Paradee-8M-v1.2
Paradee-8M-v1.2 is an update to Sahil Mahendrakar's small text-to-speech model, which is distilled from Kokoro-82M.
 Open ↗
Who
Who is an on-device speaker diarization model from Desert Ant Labs that labels who spoke when in audio and video,…
 Open ↗
Dessa
Moved from Week 44.
 Open ↗
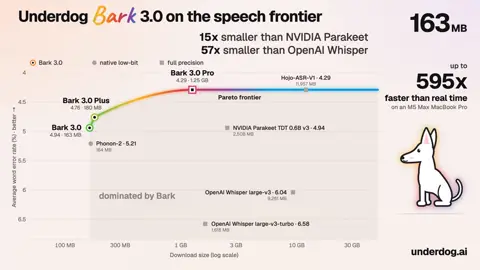
Ming-3.0-tts
An open-weight text-to-speech family from Ant Group's Inclusion AI with voice design from a text description, voice…
 Open ↗
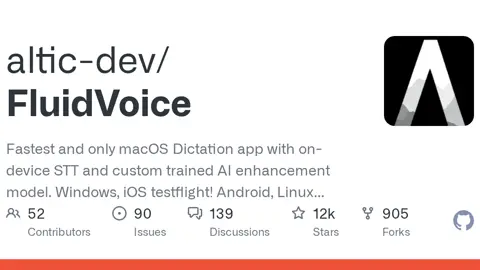
Underdog Bark 3.0
An English speech-to-text model family that runs on-device in the Underdog Mac app for dictation and meeting notes,…
 Open ↗
FluidVoice 1.6.11
A free, open-source dictation app for macOS, at fluidvoice.com, that runs speech recognition on the device, with its…
 Open ↗
KittenTTS 2
A 1.7B speech language model that writes codec tokens a vocoder turns into 24 kHz audio, a new model from the team…
 Open ↗
Fish Audio Drama 3
Fish Audio's new flagship speech model, launched 13 October and following Fish Audio S2 (covered in week 11), built for…
 Open ↗
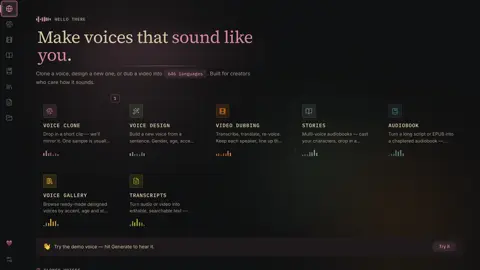
VoiceStudio v0.5.6
Since Week 37 2026: the local, open-source ElevenLabs alternative for voice cloning, voice design, dubbing, dictation,…
 Open ↗
WorldSonus
An interactive video-to-audio model, posted 6 October with code and weights, that adds synchronized stereo sound to…
 Open ↗
Bhojpuri F5-TTS
A rank-32 LoRA (10.1M of 347M parameters trainable) on AI4Bharat's IndicF5, trained on 9.4 hours of IISc's SYSPIN…
 Open ↗
Phonon-2
An open-weight English speech recognition model compressed from NVIDIA's Parakeet TDT 0.6B v3, with weights uploaded on…
- Open ↗
Whistle
Cactus's speech recognition model for small devices, released 2 October as the companion to Needle 3 (covered here in…
 Open ↗
MAI Playground
Since Week 24 2026: Microsoft's limited-preview playground now hosts MAI-Transcribe-2, MAI-Voice-2.1, MAI-Image-2.6 and…
 Open ↗
Eleven v4 and v4 Turbo
ElevenLabs' new text-to-speech models, released 28 September: Eleven v4, its most expressive model, and Eleven v4…
 Open ↗
Gemini 3.8 Flash TTS
Two new text-to-speech models, Flash and Flash-Lite, improving on Gemini 3.1 Flash TTS with better long-form content,…
- Open ↗
OpenLess v2.0.0-Beta.1
A cross-platform voice input tool, Rust core with Tauri on macOS, Windows and Android and egui on Linux, that…
- Open ↗
Pocket TTS Training Guide
A training guide inside the pocket-tts repository explaining how to train a custom model on your own GPU and speech…
- Open ↗
R2T2
Open-source streaming speech recognition for real-time transcription in English and Mandarin, with code on GitHub and…
- Open ↗
YuE2
Moved from Week 37 2026, where it was covered from the project page.
- Open ↗
Qwen3.8-LiveTranslate
Simultaneous interpretation built on an interleave architecture with a hybrid mixture-of-experts backbone split into…
- Open ↗
Gemini 3.8 Live
A real-time conversational voice model with near real-time visual grounding across 97 languages, including switching…
- Open ↗
Suno v6
Three models at once: v6 for precision and control, v6-wild for open-ended exploration, and v6-mini for everyone,…
- Open ↗
AuK
A 1.5B foundational model unifying speech generation and editing through natural-language instructions and audio…
- Open ↗
VoxCPM2
Tokenizer-free TTS: an end-to-end diffusion-autoregressive architecture generating continuous speech representations…
- Open ↗
Realtime TTS-2
Conditions on multi-turn audio history rather than a single sentence, inferring emotional state, tone and pacing from…
- Open ↗
Breeze TTS 2
Released 7 August as the successor to BreezeBlue's first TTS, aimed at interactive voice work in games, animation and…